<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.1.1">Jekyll</generator><link href="https://y.tsutsumi.io/feed/index.xml" rel="self" type="application/atom+xml" /><link href="https://y.tsutsumi.io/" rel="alternate" type="text/html" /><updated>2026-09-04T00:06:15+00:00</updated><id>https://y.tsutsumi.io/feed/index.xml</id><title type="html">Yusuke Tsutsumi</title><subtitle>My blog on software, productivity, and obsessively optimizing. I work at Google, ex-Zillow. Thoughts my own.</subtitle><entry><title type="html">Calculating and achieving peak TOPS on the DGX Spark</title><link href="https://y.tsutsumi.io/peak-tops-dgx-spark/" rel="alternate" type="text/html" title="Calculating and achieving peak TOPS on the DGX Spark" /><published>2026-07-20T07:00:00+00:00</published><updated>2026-07-20T07:00:00+00:00</updated><id>https://y.tsutsumi.io/figuring-out-actual-flops</id><content type="html" xml:base="https://y.tsutsumi.io/peak-tops-dgx-spark/"><![CDATA[<p>You’ll often see “peak TOPS” advertised for accelerators like GPUs - but where does that number come from, and can we achieve it? Let’s break it down using the DGX Spark’s 1000 TOPS as an example.</p>

<p>Peak TOPS refers to trillions of floating point operations per second - but in the case of accelerators like NVIDIA GPUs, that number is almost always in reference to an MMA operation - performing matrix multiplication and accumulating the results.</p>

<p>It’s also worth noting that TOPS is always in the context of a specific <em>precision</em> - the data type that you’re operating on. Many vendors now report peak TOPS in a smaller data type used in quantized data formats such as FP8, INT8, or as low as FP4 (or per-block precision like NVFP4).</p>

<p>In addition, oftentimes TOPS are now reported using “sparse” TOPS - which assumes that the underlying matrix being multiplied has a pattern of zero or near-zero values that would effectively skip the multiplication entirely. It’s often ratios of 2:1 sparsity, so when we see reports of “X TOPS”, it’s X/2. So in the case of DGX, we should target roughly 500 TOPS.</p>

<p>Can we derive this number? For NVidia blackwell GPUs, the TOPS match this equation:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>SM_COUNT * TENSOR_CORES_PER_SM * TENSOR_CORE_FLOPS_PER_CYCLE * CLOCK_SPEED
</code></pre></div></div>

<p>Substituting the Blackwell architecture parameters for the GB10 GPU:</p>

<ul>
  <li>SMs = 48</li>
  <li>Tensor Cores per SM = 4</li>
  <li>Tensor Core FP4 FLOPS per cycle = 2048</li>
  <li>Clock Speed = 2.418 GHz</li>
</ul>

<p>Substituting these values into the equation above:</p>

<p>Peak FP4 = 48 SMs * 4 Tensor Cores/SM * 2048 FLOPs/Core/Clock * 2.418 * 10^9 Hz
Peak FP4 = 950,273,280,000 operations per second ~= 950.27 TFLOPS</p>

<p>But of course those are reported as sparse TOPS, so we halve the value:</p>

<p>Sparse FP4 = Peak FP4 / 2
Sparse FP4 = 475,136,640,000 operations per second ~= 475.14 TFLOPS</p>

<p>To achieve this, however, you need to make sure you’re maximizing the number of values you can fit in the registers of the tensor core as well. Specifically, you have to use the <code class="language-plaintext highlighter-rouge">mma.sync.aligned.kind::mxf4nvf4.block_scale.scale_vec</code> matrix multiply instruction, ensuring that you don’t pad additional bits in the register, using only the required 4 bits per element. Otherwise, for example with 8 bit padding, you’re effectively halving the utilization of the tensor core.</p>

<p>However, if you get all of those right, you can finally achieve max TOPS!</p>

<p>Thanks to <a href="https://github.com/secYOUre">Alfonso De Gregorio</a> for the <code class="language-plaintext highlighter-rouge">nvfp4bench</code> tool (https://github.com/secYOUre/nvfp4bench), and for sharing the final insight of the register padding slowing things down in my own benchmarks: https://github.com/toumorokoshi/yft-ml-sandbox/blob/main/cuda/gemm/experiment.md</p>

<h2 id="additional-notes">Additional Notes</h2>

<h3 id="how-to-query-hardware-parameters">How to Query Hardware Parameters</h3>

<h4 id="method-1-programmatically-querying-sm-count-and-clock-speed-via-cuda-api">Method 1: Programmatically Querying SM Count and Clock Speed via CUDA API</h4>

<p>You can write a simple CUDA program querying the <a href="https://docs.nvidia.com/cuda/cuda-runtime-api/group__CUDART__DEVICE.html#group__CUDART__DEVICE_1g1bf2e920221402b11ede84cf7cc60dc1">cudaGetDeviceProperties</a> API to retrieve these hardware specifications directly:</p>

<div class="language-cpp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="cp">#include</span> <span class="cpf">&lt;stdio.h&gt;</span><span class="cp">
#include</span> <span class="cpf">&lt;cuda_runtime.h&gt;</span><span class="cp">
</span>
<span class="kt">int</span> <span class="nf">main</span><span class="p">()</span> <span class="p">{</span>
    <span class="n">cudaDeviceProp</span> <span class="n">prop</span><span class="p">;</span>
    <span class="kt">int</span> <span class="n">deviceId</span> <span class="o">=</span> <span class="mi">0</span><span class="p">;</span> <span class="c1">// Target GPU device ID</span>

    <span class="k">if</span> <span class="p">(</span><span class="n">cudaGetDeviceProperties</span><span class="p">(</span><span class="o">&amp;</span><span class="n">prop</span><span class="p">,</span> <span class="n">deviceId</span><span class="p">)</span> <span class="o">==</span> <span class="n">cudaSuccess</span><span class="p">)</span> <span class="p">{</span>
        <span class="n">printf</span><span class="p">(</span><span class="s">"GPU Device: %s</span><span class="se">\n</span><span class="s">"</span><span class="p">,</span> <span class="n">prop</span><span class="p">.</span><span class="n">name</span><span class="p">);</span>
        <span class="n">printf</span><span class="p">(</span><span class="s">"SM Count (multiProcessorCount): %d</span><span class="se">\n</span><span class="s">"</span><span class="p">,</span> <span class="n">prop</span><span class="p">.</span><span class="n">multiProcessorCount</span><span class="p">);</span>

        <span class="kt">int</span> <span class="n">clockRateKHz</span> <span class="o">=</span> <span class="mi">0</span><span class="p">;</span>
        <span class="c1">// Query clock rate attribute (cudaDevAttrClockRate)</span>
        <span class="k">if</span> <span class="p">(</span><span class="n">cudaDeviceGetAttribute</span><span class="p">(</span><span class="o">&amp;</span><span class="n">clockRateKHz</span><span class="p">,</span> <span class="n">cudaDevAttrClockRate</span><span class="p">,</span> <span class="n">deviceId</span><span class="p">)</span> <span class="o">==</span> <span class="n">cudaSuccess</span><span class="p">)</span> <span class="p">{</span>
            <span class="n">printf</span><span class="p">(</span><span class="s">"Clock Rate (cudaDevAttrClockRate): %d kHz (%.3f GHz)</span><span class="se">\n</span><span class="s">"</span><span class="p">,</span> <span class="n">clockRateKHz</span><span class="p">,</span> <span class="n">clockRateKHz</span> <span class="o">/</span> <span class="mf">1e6</span><span class="p">);</span>
        <span class="p">}</span>
    <span class="p">}</span>
    <span class="k">return</span> <span class="mi">0</span><span class="p">;</span>
<span class="p">}</span>
</code></pre></div></div>

<h4 id="inspecting-compute-capability-via-nvidia-smi">Inspecting Compute Capability via nvidia-smi</h4>

<p>You can query the GPU model name and its CUDA Compute Capability from the command line:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>nvidia-smi <span class="nt">--query-gpu</span><span class="o">=</span>name,compute_cap <span class="nt">--format</span><span class="o">=</span>csv
</code></pre></div></div>
<p>For example, this returns <code class="language-plaintext highlighter-rouge">NVIDIA GB10, 12.1</code>. Once you have the Compute Capability, you can reference the <a href="https://developer.nvidia.com/cuda-gpus">NVIDIA Developer CUDA GPUs Page</a> and the <a href="https://docs.nvidia.com/cuda/cuda-c-programming-guide/index.html#features-and-technical-specifications">NVIDIA CUDA C++ Programming Guide Architecture Specs</a> to look up the exact SM counts and Tensor Core properties.</p>

<h2 id="references">References</h2>

<ul>
  <li><strong>Information about SM / Tensor Core counts:</strong> https://chipsandcheese.com/p/analyzing-nvidia-gb10s-gpu</li>
  <li><strong>NVIDIA Blackwell Architecture Whitepaper:</strong> <a href="https://images.nvidia.com/aem-dam/Solutions/Data-Center/blackwell/nvidia-blackwell-gpu-architecture-whitepaper.pdf">NVIDIA Blackwell GPU Architecture Whitepaper</a> - Core specifications for SM counts, fifth-generation Tensor Cores, and FP4 throughput metrics.</li>
</ul>]]></content><author><name></name></author><category term="coding" /><summary type="html"><![CDATA[You’ll often see “peak TOPS” advertised for accelerators like GPUs - but where does that number come from, and can we achieve it? Let’s break it down using the DGX Spark’s 1000 TOPS as an example.]]></summary></entry><entry><title type="html">Playing around with Local LLMs</title><link href="https://y.tsutsumi.io/playing-with-local-llms/" rel="alternate" type="text/html" title="Playing around with Local LLMs" /><published>2026-07-13T07:00:00+00:00</published><updated>2026-07-13T07:00:00+00:00</updated><id>https://y.tsutsumi.io/playing-with-local-llms</id><content type="html" xml:base="https://y.tsutsumi.io/playing-with-local-llms/"><![CDATA[<p>Like many, I’ve started to get really bullish on the future of local LLMs - the open models and weights are getting better every few weeks. Qualitatively, I think it’s still abundantly clear that local LLMs are not at par with the larger hosted models for my high-priority use cases like coding.</p>

<p>That all said, it’s a matter of time.</p>

<h2 id="how-do-you-run-local-llms">How do you run local LLMs?</h2>

<p><a href="https://github.com/ggml-org/llama.cpp">llama.cpp</a> has been a good harness:</p>

<ul>
  <li>It’s able to run most of the modern models without issue.</li>
  <li>It has a simple command, <code class="language-plaintext highlighter-rouge">llama-server</code>, for serving the model text-completion API interface that is commonly used by harnesses.</li>
</ul>

<p>Using it is as simple as downloading the <a href="https://github.com/ggml-org/llama.cpp/releases">prebuilt binaries</a> from the GitHub. More ideally you build from source, which can sometimes improve support for your GPU as the build can detect it and compile itself appropriately.</p>

<p>llama.cpp works with models that are saved in the gguf format. I’ve found that <a href="https://huggingface.co/unsloth">unsloth.ai</a>’s <a href="https://huggingface.co/unsloth">huggingface collections</a> have most models I’ve wanted to try.</p>

<p>I grab a model and serve it from my NVidia Spark DGX at port <code class="language-plaintext highlighter-rouge">0.0.0.0</code> so my other machines can access it:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>llama-server <span class="nt">-hf</span> unsloth/gemma-4-E4B-it-GGUF:UD-Q4_K_XL <span class="nt">-h</span> 0.0.0.0
</code></pre></div></div>

<h2 id="what-impacts-the-runtime-latency-of-a-model">What impacts the runtime latency of a model</h2>

<p>A critical aspect of local models is the runtime latency - I think roughly 60 tokens / second is the sweet spot, producing a good amount of code quickly without having to shift my focus for long periods of time.</p>

<p>It’s a bit reductionist to boil things down to a few specific parameters, but with the model’s I’ve been testing I think the general factors I see are:</p>

<ul>
  <li>Total size of the weights: a combination of total parameter count * data format (fp16, fp8, int8, and lower). Running models with larger weights is bottle-necked by the total amount of dram that your GPU supports (i.e. the DGX spark has 128GB of unified memory available).</li>
  <li>The size of the effective weights: using techniques like mixture of experts, not all weights are utilized on each inference run. Although the weights still need to be loaded into dram to ensure they can be quickly read for each token prediction. This is limited by memory bandwidth to load the values by GPU, or in rarer cases the tops.</li>
</ul>

<h2 id="what-models-work-well">What models work well?</h2>

<h3 id="qwen36-27b">Qwen3.6-27b</h3>

<p>I’ve heard this is a great model, but the 7-8 token/s were not enough for me to be truly productive: especially with the amount of thinking it does, it barely gets to a tool call within the span of 10 minutes. Even with multi-token-prediction (MTP) where a speedup is expected, it is just too slow.</p>

<h3 id="qwen3-code-next">Qwen3-code-next</h3>

<p>I’ve found that this has been fairly productive - at 60+ tok/s it’s able to produce code efficiently, and call tools appropriately. I’ve had it write a couple changes to vs code extensions, or add features to fairly large frontend applications.</p>

<p>It is definitely not as robust as my go-tos: Cursor’s default and Gemini flash 3.5 medium: both can make these changes and test them without issue.</p>

<h2 id="where-do-local-models-fall-short">Where do local models fall short?</h2>

<p>Despite my enthusiasm, local models are still no where near good enough to replace all use cases I have for larger models. Examples include:</p>

<ul>
  <li>Getting stuck into loops: even on relatively simple solutions (remove all translucent panels in this react page), it will get stuck in a loop where it redoes and undoes the change, because it keeps second-guessing itself.</li>
  <li>Requiring very specific instructions: with models like Gemini-3.5-medium I can just say “add a copy to jira link on the issue page”. With Qwen3-coder-next I have to give a precise list of steps, sometimes mentioning what files to touch.</li>
  <li>With all the local models I’ve tried, I’ve had to give specific feedback after the change as well - in some cases the feature is entirely incorrect (e.g. access to the Jira API doesn’t work).</li>
</ul>

<p>But in some cases it’s able to read the codebase, produce fixes, and resolve them without personal intervention. I couldn’t imagine a local model that I can run on a tiny computer on my desk being capable of that a year ago.</p>

<h2 id="conclusion">Conclusion</h2>

<p>Although local LLMs aren’t all I need <em>yet</em>, it’s very easy to see a future where that may be the case. It’s going to be a combination of:</p>

<ul>
  <li>Better models that need fewer weights to achieve similar benchmarks.</li>
  <li>Increased memory storage to enable models with a larger number of total parameters.</li>
  <li>Increased memory bandwidth and/or flops to enable running models at much faster tokens / second for larger effective weights.</li>
</ul>

<h2 id="side-quest-profiling-my-gpu">Side quest: Profiling my GPU</h2>

<p>I really wanted to get Qwen 3.6 working, so I tried to profile the execution of the model. To do so on an NVidia GPU, one can use Nvidia Nsight Systems to get a sense of the kernels that have the longest runtime:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>nsys <span class="nt">-o</span> llama_profile ./build/bin/llama-cli <span class="nt">-hf</span> <span class="k">${</span><span class="nv">MODEL</span><span class="k">}</span> <span class="nt">-p</span> <span class="s2">"The quick brown fox"</span> <span class="nt">-n</span> 5 <span class="nt">--no-conversation</span>
</code></pre></div></div>

<p>Then produce a match that looks at the specific kernels in question:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">sudo</span> <span class="nt">-E</span> /usr/local/cuda/bin/ncu <span class="nt">-f</span> <span class="nt">-k</span> regex:<span class="s1">'(quantize_q8_1|mul_mat_vec_q|k_bin_bcast|k_get_rows_float)'</span> <span class="nt">-o</span> <span class="nv">$PWD</span>/llama_profile_report ~/bin/llama-completion <span class="nt">-hf</span> <span class="k">${</span><span class="nv">MODEL</span><span class="k">}</span> <span class="nt">-p</span> <span class="s2">"The quick brown fox"</span> <span class="nt">-n</span> 1 <span class="nt">-no-cnv</span>
</code></pre></div></div>

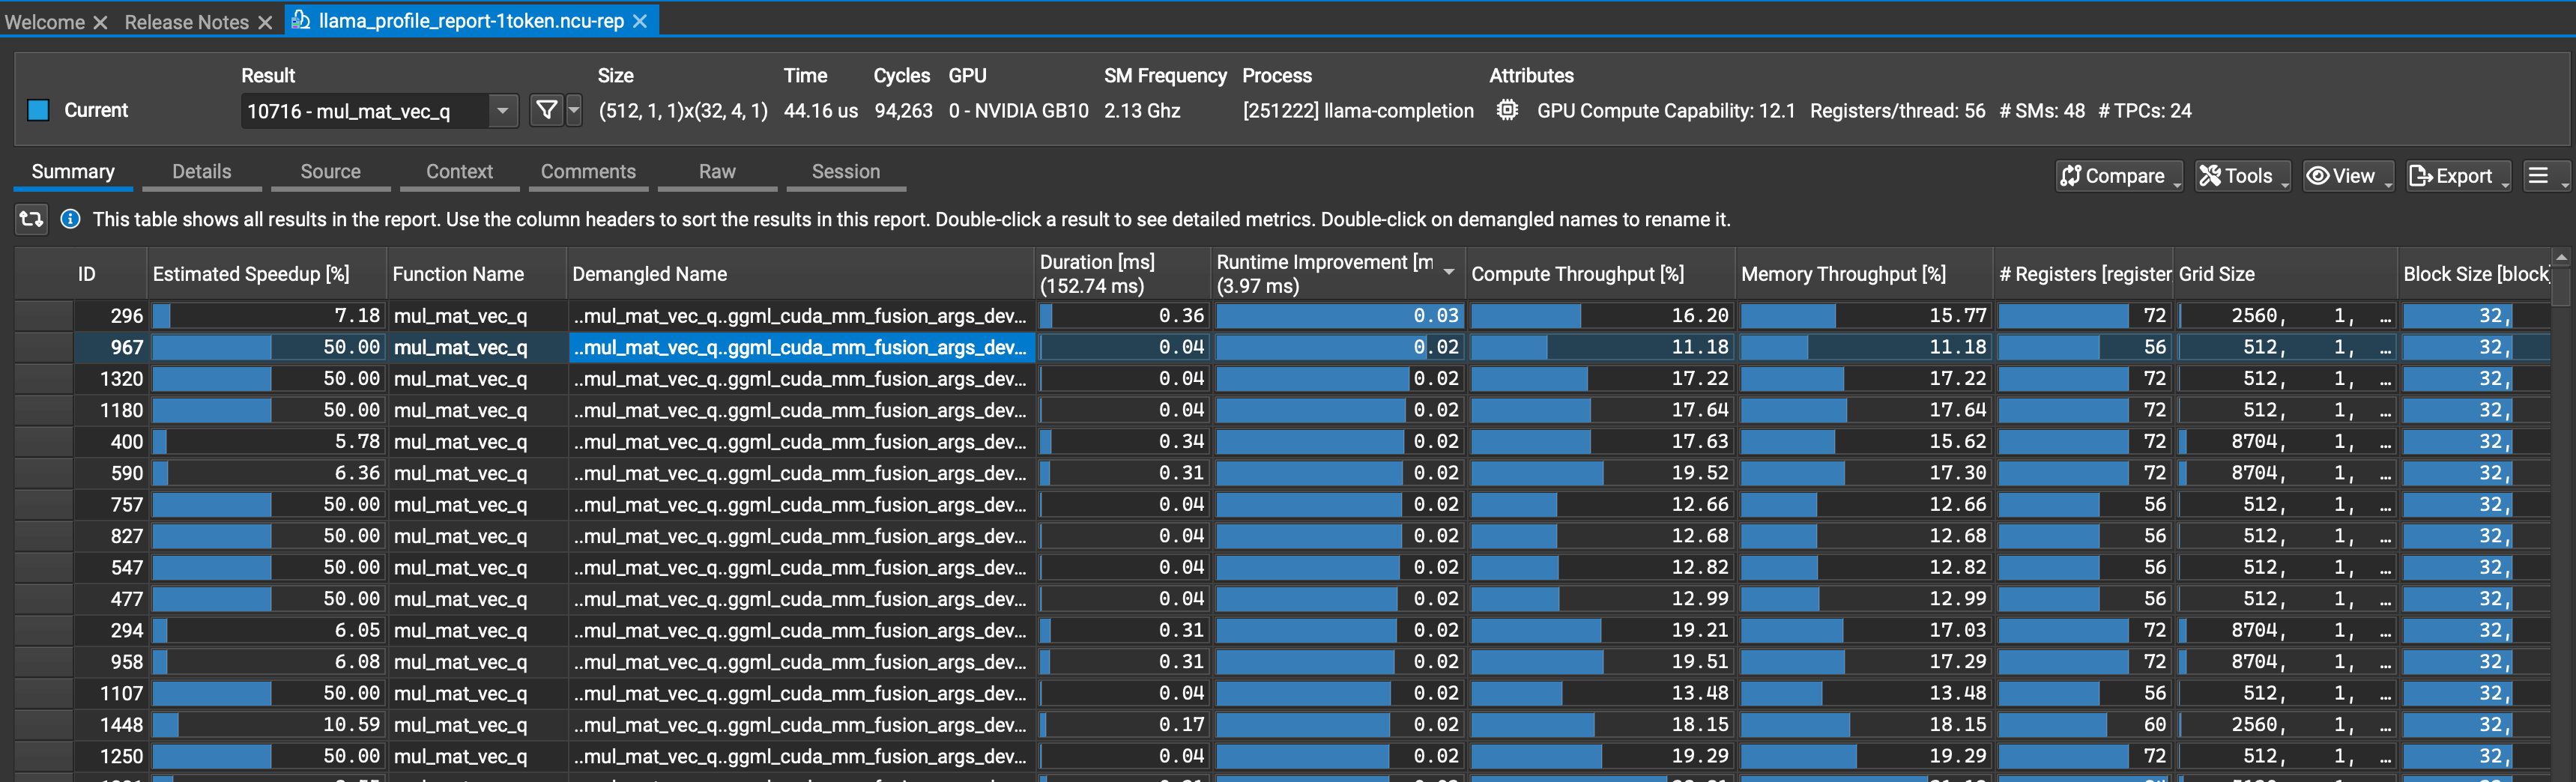
<p>What’s interesting about this investigation is that I found that the workload is neither saturating compute nor memory bandwidth - the SM activation actually seems to be somewhat uneven, perhaps due to sparse matrix multiplication. Something I plan on looking at, with a write up in the future.</p>

<p><img src="../../assets/2026-07-13-playing-with-local-llms.png" alt="" /></p>

<h2 id="references">References</h2>]]></content><author><name></name></author><category term="coding" /><summary type="html"><![CDATA[Like many, I’ve started to get really bullish on the future of local LLMs - the open models and weights are getting better every few weeks. Qualitatively, I think it’s still abundantly clear that local LLMs are not at par with the larger hosted models for my high-priority use cases like coding.]]></summary></entry><entry><title type="html">Thoughts on Subpaths in AEPs</title><link href="https://y.tsutsumi.io/aep-subpaths/" rel="alternate" type="text/html" title="Thoughts on Subpaths in AEPs" /><published>2026-07-06T07:00:00+00:00</published><updated>2026-07-06T07:00:00+00:00</updated><id>https://y.tsutsumi.io/aep-subpaths</id><content type="html" xml:base="https://y.tsutsumi.io/aep-subpaths/"><![CDATA[<h2 id="problem">Problem</h2>

<p>The primary problem has to do with AEP-compliant APIs that have a subpath prefix. An example is something like:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>api.example.com/users/v1
</code></pre></div></div>

<p>Here the resource path starts <em>after</em> a constant prefix in the API.</p>

<p>The question is: should APIs with a path prefix like this be allowed? and if so, how should the clients and consumers handle this?</p>

<h2 id="should-apis-with-path-prefixes-be-allowed">Should APIs with path prefixes be allowed?</h2>

<p>Even today, having a path prefix is a very common attribute in APIs. Therefore, I don’t see much of an option here but to allow these.</p>

<p>Examples include:</p>

<ul>
  <li>The Google APIs, which are always <a href="https://cloud.google.com/iam/docs/reference/rest/">wrapped with a version prefix</a>.</li>
  <li>The Roblox Cloud APIs, prefixed with a <a href="https://create.roblox.com/docs/en-us/cloud/features/groups">version and cloud prefix</a>.</li>
</ul>

<p>To exclude these APIs from compliance because their existence of a prefix would significantly hamper the adoption of the AEPs.</p>

<p>Therefore, I think the choice to include support for this is more of a practical choice than one taken for an ideal design.</p>

<h2 id="problems-with-a-path-prefix">Problems with a path prefix</h2>

<p>Introducing this pattern, however, comes with challenges. Enumerating the difficulties, those are:</p>

<h3 id="a-path-prefix-breaks-the-collectionresource-pattern">A path prefix breaks the collection/resource pattern</h3>

<p>The main issue with a prefix comes with the ability to semantically interpret the meaning of a path. The resource model in the AEP specific includes a pattern of collection, resource id elements. For example, take a book in a bookshelf:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>/bookshelves/living-room/books/pride-and-prejudice.
</code></pre></div></div>

<p>From here, it’s very easy to understand the following:</p>

<ul>
  <li>there are two collections of resources: <code class="language-plaintext highlighter-rouge">bookshelves</code> and <code class="language-plaintext highlighter-rouge">books</code>.</li>
  <li><code class="language-plaintext highlighter-rouge">books</code> are a subcollection under a bookshelf.</li>
  <li>The bookshelf in question is <code class="language-plaintext highlighter-rouge">living-room</code>, while the book in question is <code class="language-plaintext highlighter-rouge">pride-and-prejudice</code>.</li>
</ul>

<p>If we add a prefix, say, <code class="language-plaintext highlighter-rouge">cloud/v1</code>:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>/cloud/v1/bookshelves/living-room/books/pride-and-prejudice
</code></pre></div></div>

<p>Now there is some ambiguity: is <code class="language-plaintext highlighter-rouge">v1</code> a cloud? Although this is immediately obvious to a human, to a machine there is no longer a discrete algorithm to extract collections and elements.</p>

<h2 id="addressing-the-problems">Addressing the problems</h2>

<p>Although the above brings up more abstract problems, we need to look at how to resolve them discretely. Thinking through where there are practical challenges:</p>

<h3 id="how-to-reference-a-resource">How to reference a resource</h3>

<p>For a <em>resource reference</em>, the path to the resource is used. Should this resource include the path prefix, or no?</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    # with the prefix
    book: "/cloud/v1/bookshelves/living-room/books/pride-and-prejudice",
    # without
    book: "bookshelves/living-room/books/pride-and-prejudice",
</code></pre></div></div>

<p>For protobuf APIs in the AEPs, the path of the resource is used directly in operations such as Get / Update / Delete. Therefore, it does not need the prefix.</p>

<p>For <em>REST</em> JSON APIs, the reference will probably, at some point, be used to reconstruct the full path. For example, a backend may perform a GET on the HTTP path of the resource to retrieve information about it. However, resolving that resource reference would require some knowledge of the API domain to begin with, so it wouldn’t be a stretch to <em>also</em> intern the path.</p>

<p>The biggest issue is with <em>full resource paths</em> - examples where a resource references another resource in a different API. However, that too could also be solved by
including the full path, including the api name, which in turn would also include the path prefix:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>{api name}/{resource path}
{api.example.com/cloud/v1}/{bookshelves/living-room/books/pride-and-prejudice}
</code></pre></div></div>

<p>So there are cases well handled as well.</p>

<h2 id="conclusion">Conclusion</h2>

<p>To support subpaths in API, I propose the following:</p>

<ol>
  <li>full resource paths to other APIs <em>always</em> include the api name: this enables clients to retrieve the resource without knowledge of where the API description of that separate API exists.
    <ol>
      <li>alternatively, the API <em>could</em> describe the API name it expects via an annotation. This would allow a client to resolve that path.</li>
    </ol>
  </li>
  <li>modify the API names description to clarify that it can include a sub-path.
    <ol>
      <li>this also solves a separate problem, where an API may have resources tightly coupled to a separate path.</li>
    </ol>
  </li>
</ol>]]></content><author><name></name></author><category term="coding" /><summary type="html"><![CDATA[Problem]]></summary></entry><entry><title type="html">Thoughts on allow_missing in AEPs</title><link href="https://y.tsutsumi.io/aep-allow-missing/" rel="alternate" type="text/html" title="Thoughts on allow_missing in AEPs" /><published>2026-06-29T07:00:00+00:00</published><updated>2026-06-29T07:00:00+00:00</updated><id>https://y.tsutsumi.io/aep-allow-missing</id><content type="html" xml:base="https://y.tsutsumi.io/aep-allow-missing/"><![CDATA[<p>The main concern I have with <code class="language-plaintext highlighter-rouge">allow_missing</code> is duplication. Does it overlap with some existing api, such as the new apply method?</p>

<p>I could imagine there’s some differences:</p>

<ul>
  <li>If a field is missing, an apply could reject the request, while update with allow_missing would silently accept it with some default.</li>
</ul>

<p>Today, apply with fields missing does not actually state that the request should be rejected. Instead, it states:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Note that PUT requests with fields missing in the resource may result in overwriting values in the resource with existing values. For that reason, AEP-compliant APIs generally use the PATCH HTTP verb.
</code></pre></div></div>

<p>So the behavior is actually one of:</p>

<ul>
  <li>use the default values for those fields.</li>
  <li>do not modify the existing one.</li>
</ul>

<p>But does not clarify which is expected. This should be fixed regardless.</p>

<p>If the choice is to leave unset values unmodified, that it is identical to the behavior of update with <code class="language-plaintext highlighter-rouge">allow_missing</code>.</p>

<p>If default values are chosen, then in proto, that would be nearly identical to an update with a full field mask set (a wildcard <code class="language-plaintext highlighter-rouge">*</code>).</p>

<p>But thinking a bit about that second user journey, generally the idea that one would like to <em>reset</em> a resource back to it’s default values is somewhat non-sensical:</p>

<ul>
  <li>If one would like to update a resource back to it’s default, set it explicitly in your update.</li>
  <li>If you would like to leave the value alone, leave it unset.</li>
</ul>

<p>This is a relatively easy thing to accomplish in OAS: one can examine the fields in a resource, see if they are unset, and then in turn only modify the ones that are set.</p>

<p>For protobuf, this is a bit more difficult because of the fact that non-optional fields are set to their default values. However, even there I think there’s a solution: effectively make every protobuf field explicitly optional, at which point it behaves just like json.</p>

<p>In the above case, one can just set the fields they would like to modify, or are aware of. Combined with a field mask, this would determine wet</p>

<h2 id="user-journeys">User journeys</h2>

<table>
  <thead>
    <tr>
      <th>What you’re trying to do with a field</th>
      <th>how to accomplish it in protobuf</th>
      <th>how to do it in REST</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Set a field to empty</td>
      <td>include it in the field mask, set field as null</td>
      <td>set value as none</td>
    </tr>
    <tr>
      <td>Don’t modify a field</td>
      <td>don’t include the field in the field mask, set field as null</td>
      <td>don’t include value in json payload</td>
    </tr>
    <tr>
      <td>Set a field to a specific value</td>
      <td>include the field in the field mask, set field with desired value</td>
      <td>include value in json payload</td>
    </tr>
  </tbody>
</table>

<h2 id="conclusions">Conclusions</h2>

<p>Ultimately, <code class="language-plaintext highlighter-rouge">allow_missing</code> and update, due to it’s inclusion of field masks, are a more flexible version of the apply method. Generally clients should just use that method across the board.</p>

<p>In addition, the following guidance should probably be added:</p>

<ul>
  <li>update protobuf guidance that all fields should be optional.</li>
  <li>the apply field should clarify whether it will use default values if a field is missing, or leave the field unmodified.</li>
  <li>the apply field should clarify that a request with required fields missing will reject the response.</li>
</ul>]]></content><author><name></name></author><category term="coding" /><summary type="html"><![CDATA[The main concern I have with allow_missing is duplication. Does it overlap with some existing api, such as the new apply method?]]></summary></entry><entry><title type="html">Thoughts on Soft Delete</title><link href="https://y.tsutsumi.io/aep-soft-delete/" rel="alternate" type="text/html" title="Thoughts on Soft Delete" /><published>2026-06-22T07:00:00+00:00</published><updated>2026-06-22T07:00:00+00:00</updated><id>https://y.tsutsumi.io/aep-soft-delete</id><content type="html" xml:base="https://y.tsutsumi.io/aep-soft-delete/"><![CDATA[<p>This document serves as a corrolary to <a href="https://github.com/aep-dev/aeps/issues/111">this issue on
aep.dev</a>, including my thoughts to
remove the soft delete pattern.</p>

<h2 id="the-background">The background</h2>

<p>As of 2025-09-13, the aeps have a pattern in which one can “soft delete” a
resource - where it not actually removed from a collection, but is actually
flagged as deleted. This allows the resource to be recoverable later.</p>

<p>The soft delete pattern, I believe, exists to serve the purpose of situations
where recovery is desired, such as most situations where persistent data is
stored:</p>

<ul>
  <li>A database, where recreating the resource does not restore any valuble data
stored.</li>
  <li>A filesystem, where a file may need to be recovered after the fact.</li>
</ul>

<h2 id="the-implementation-of-soft-delete-today">The implementation of soft delete today</h2>

<p>The current implementation of AEPs’ soft delete boils down to the following:</p>

<ol>
  <li>a new custom method, <code class="language-plaintext highlighter-rouge">undelete</code>, on the resource.</li>
  <li>an added field <code class="language-plaintext highlighter-rouge">show_deleted</code> to the <code class="language-plaintext highlighter-rouge">List</code> standard method, where resources
are hidden unless specified.</li>
  <li>an added field <code class="language-plaintext highlighter-rouge">show_deleted</code> to the <code class="language-plaintext highlighter-rouge">Get</code> standard method, where the resource will
return 410 without it.</li>
</ol>

<p>There are a few other details (such as the usage of expiry_date) that are
additional, but do not force any additional fields on the standard methods.</p>

<h2 id="the-problems-soft-delete-is-not-compatible-with-declarative-clients">The problems: soft delete is not compatible with declarative clients</h2>

<p>Declarative clients expect consistent resource-oriented operations on each
resource - for simple CRUD on a resource, declarative clients are able to easily
map each operation to the resource lifecycle.</p>

<pre><code class="language-mermaid">graph LR
  exists
  not_exists
  exists -- "update" --&gt; exists
  not_exists -- "create" --&gt; exists
  exists -- "delete" --&gt; not_exists
</code></pre>

<p>For soft delete, where would that fit in? Effectively it creates another state - soft deleted.</p>

<pre><code class="language-mermaid">graph LR
  exists
  soft_deleted
  not_exists
  not_exists -- "create" --&gt; exists
  exists -- "update" --&gt; exists
  soft_delete -- "undelete" --&gt; exists
  soft_delete -- "expiry hit" --&gt; not_exists
</code></pre>

<p>But this may also result in weird cases like:</p>

<p>A resource “create” throwing an error because the resource is soft-deleted, and
therefore exists. But a get would return a 404.</p>

<h2 id="proposed-alternative">Proposed alternative</h2>

<p>Since the primary use case is about backing up and enabling restoration of data,
the proposal would be to replace these augmentations on the primary resource, to
adding a second resource for “backups” or “snapshots”.</p>

<p>The pattern would look something like:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>/database/foo
/database-snapshots/foo/snapshots/latest
</code></pre></div></div>

<p>The database-snapshot could be support a custom method, <code class="language-plaintext highlighter-rouge">restore</code>, that would be
similar to undelete and bring an old resource back.</p>

<p>This would be similar to the <a href="https://aep.dev/162/">resource revision</a> pattern -
where a design pattern is introduced by adding a new resource, not by augmenting
standard methods.</p>]]></content><author><name></name></author><category term="coding" /><summary type="html"><![CDATA[This document serves as a corrolary to this issue on aep.dev, including my thoughts to remove the soft delete pattern.]]></summary></entry><entry><title type="html">Local, Parallel, and Autonomous: Building a Fully Agent-Generated Codebase</title><link href="https://y.tsutsumi.io/2026/03/30/agentic-orchestration-with-beads-and-lelouch/" rel="alternate" type="text/html" title="Local, Parallel, and Autonomous: Building a Fully Agent-Generated Codebase" /><published>2026-03-30T07:00:00+00:00</published><updated>2026-03-30T07:00:00+00:00</updated><id>https://y.tsutsumi.io/2026/03/30/agentic-orchestration-with-beads-and-lelouch</id><content type="html" xml:base="https://y.tsutsumi.io/2026/03/30/agentic-orchestration-with-beads-and-lelouch/"><![CDATA[<p>I’ve started a video series on agentic coding, and you can view the first video <a href="https://youtu.be/dXyPfslMLYE?si=uRz0qamR3sqWTW0i">here</a>. This is a short summary if you prefer a post instead!</p>

<p>The agentic workflow is something I’m calling “local, parallel, and autonomous”.
It’s a dive deep into making a whole codebase from scratch, completely
hands-off.</p>

<h4 id="the-core-attributes">The Core Attributes</h4>

<p>The main pillars for this workflow are straightforward:</p>

<ul>
  <li><strong>Local:</strong> All the git worktrees run locally on my machine, avoiding the complications of remote execution.</li>
  <li><strong>Parallel:</strong> It’s built to scale so multiple agents can work on different issues across multiple worktrees at the same time.</li>
  <li><strong>Autonomous:</strong> The agents complete issues from start to finish without human intervention.</li>
</ul>

<h4 id="choosing-the-right-projects">Choosing the Right Projects</h4>

<p>Let’s be clear: as of March 2026, there are a <em>lot</em> of risks with this approach. I wouldn’t confidently build and deploy a production SaaS web application this way because the necessary guardrails for safety and privacy requirements just aren’t there yet.</p>

<p>Because of that, I choose self-contained, smaller projects. I’ve built a few codebases this way, including:</p>

<ul>
  <li>Small VS Code extensions (one to <a href="https://github.com/toumorokoshi/vscode-hivemind">synchronize my dotfiles</a>, another to add missing file operations).</li>
  <li>A self-contained GitHub page that <a href="https://github.com/toumorokoshi/paste-as-simple-markdown">converts LaTeX to Markdown and plaintext</a>.</li>
  <li><a href="https://github.com/toumorokoshi/lelouch/tree/main/docs">Lelouch</a>, the workload orchestrator I use for this very process.</li>
</ul>

<p>For more complex, large-scale systems, I still rely heavily on a manual cycle where the AI generates code and I heavily review it.</p>

<h4 id="bootstrapping-setting-the-guardrails">Bootstrapping: Setting the Guardrails</h4>

<p>To get things started, I wrote a repository called <a href="https://github.com/toumorokoshi/agentic-bootstrap">agentic-bootstrap</a> to provide the scaffolding. Inside its <code class="language-plaintext highlighter-rouge">templates/</code> directory, I keep generic rules that help agents stay on the rails.</p>

<p>The bootstrap relies on a few key components:</p>

<ul>
  <li><strong>AGENTS.md:</strong> This file acts as the playbook. It tells agents to study the README first, ensures CI passes, enforces linting rules, and mandates that documentation is always updated.</li>
  <li><strong>specs/:</strong> This directory holds design specifications. Splitting the design up limits the context an agent has to load to accomplish a particular task, separating the “designer” agent from the “executor” agent.</li>
  <li><strong>Example Files:</strong> For the Heaptrack UI, I included a sample <code class="language-plaintext highlighter-rouge">.zst</code> file in the repo so the agent actually knows how to read the format it’s supposed to parse.</li>
</ul>

<h4 id="writing-specs-the-grill-approach">Writing Specs: The “Grill” Approach</h4>

<p>When it’s time to write the overall design, you can write it yourself, but I
used an approach called “grilling” to illustrate another, more agentic way to
bootstrap.</p>

<p>I tell the agent: <em>“Interview me about the purpose of this project”</em>. It asks me questions about architecture and UI, and I respond with my requirements—for example, that the app should be a purely client-side React app, include dark mode, and support drag-and-drop.</p>

<p>The agent then writes out the design documents in the <code class="language-plaintext highlighter-rouge">specs/</code> directory. I usually do a quick offline review; for instance, the agent once hallucinated some weird typography requirements asking for “Apple’s clear glass” style, which I promptly deleted.</p>

<h4 id="managing-the-queue-with-beads">Managing the Queue with Beads</h4>

<p>For the issue database, I use a tool called Beads, created by Steve Yegge. It acts as a local database for issues, supports being reused across multiple work trees, and is highly agent-friendly with support for <code class="language-plaintext highlighter-rouge">--json</code> flags.</p>

<p>You simply initialize it with <code class="language-plaintext highlighter-rouge">bd init --stealth</code>. From there, you can manage the queue:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">bd create</code> to make new issues.</li>
  <li><code class="language-plaintext highlighter-rouge">bd update {id} --status=open</code> or <code class="language-plaintext highlighter-rouge">--status=closed</code> to manage state.</li>
  <li><code class="language-plaintext highlighter-rouge">bd delete {id}</code> to remove them.</li>
</ul>

<p>I like to use a “thinking” model for a seeder prompt to write highly detailed initial issues, and I use the Beads VS Code extension to visually track what the agents are working on.</p>

<h4 id="orchestration-with-lelouch">Orchestration with Lelouch</h4>

<p>To orchestrate the workers, I wrote <a href="https://github.com/toumorokoshi/lelouch">Lelouch</a>. It’s effectively a way to run an agent, one per github worktree, pulling issues out of the Beads database.</p>

<p>To initialize it just run <code class="language-plaintext highlighter-rouge">lelouch init</code> per worktree. It monitors your
repositories, pulling open tasks from the Beads database by priority and
dispatching them.</p>

<p>I typically run Lelouch with the Gemini Flash model via CLI because it has a
more forgiving usage limit. I also add a pre-prompt like <em>“run tests, commit,
and push”</em> to make sure it follows through.</p>

<p>When I run <code class="language-plaintext highlighter-rouge">lelouch run -v</code>, the loop begins. It moves issues to “in progress” and logs the agent’s responses directly into the working notes, so I can see exactly what it’s up to. It’s incredibly satisfying to just watch the issues update in the VS Code extension while the agents hum away.</p>

<h4 id="handling-bugs-and-gaps">Handling Bugs and Gaps</h4>

<p>The process isn’t perfect. During my Heaptrack build, the agent created a <code class="language-plaintext highlighter-rouge">gaps.md</code> file but failed to actually implement the missing features. I had to manually prompt it: <em>“There are gaps in gaps.md that are not yet implemented. Please create BD issues for them.”</em>.</p>

<p>When I tested the UI, I found that the flame graph had sizing issues and the <code class="language-plaintext highlighter-rouge">.zst</code> file wasn’t loading properly.</p>

<p>Fixing this is a matter of adding issues to the command line via <code class="language-plaintext highlighter-rouge">bd q "fix the
bug with the zst file not outputting the flame graph"</code>. Lelouch immediately
picks it up in the background.</p>

<h4 id="takeaways-for-2026">Takeaways for 2026</h4>

<p>I’ve done this with four or five projects now, and having a central issue database with parallel worker agents is a scalable model.</p>

<p>I know that there’s been existing examples online of people who have done
everything from write compilers over to full web browsers, and games with
varying success. Despite that, I’m still skeptical and looking for ways to get it to be a consistent, high quality enough generator that it can be used for more production code. To get there, I think it’ll take more guardrails, especially security-related ones. Some projects are already using agents with a security persona to try to get there.</p>

<p>But all technology has to start somewhere, and this workflow serves as an interesting baseline for my process I intend to grow.</p>]]></content><author><name></name></author><category term="coding" /><summary type="html"><![CDATA[I’ve started a video series on agentic coding, and you can view the first video here. This is a short summary if you prefer a post instead!]]></summary></entry><entry><title type="html">The New AI Era</title><link href="https://y.tsutsumi.io/the-new-ai-era" rel="alternate" type="text/html" title="The New AI Era" /><published>2026-03-16T07:00:00+00:00</published><updated>2026-03-16T07:00:00+00:00</updated><id>https://y.tsutsumi.io/the-new-ai-era</id><content type="html" xml:base="https://y.tsutsumi.io/the-new-ai-era"><![CDATA[<h1 id="the-new-ai-era">The new AI Era</h1>

<p>Recently I read about <a href="https://steve-yegge.medium.com/welcome-to-gas-town-4f25ee16dd04">Steve Yegge’s post about GasTown</a>, an ecosystem of agent orchestration to go get monster-sized projects done.</p>

<p>I was a bit slow on the uptake when it came to AI: a lot of code last year was hand-written when many had already started letting agents do most of it. My thought was, at the time, the models themselves were often unable to produce a working feature. Let alone produce <em>good</em> code.</p>

<p>But only a year later, with models like Claude Opus 4.6 and Gemini 3.1 pro, these agents are generating code extremely quickly. And the code is actually… decent. It’s not mind-blowing - the agent still makes multiple stylistic mistakes, despite my prompt telling it not to:</p>

<ul>
  <li>It does not adopt functional programming methodologies, freely mixing IO with business logic.</li>
  <li>It repeats itself constantly.</li>
  <li>It often re-writes things it can use a library for.</li>
</ul>

<p>But it’s good enough where I can get into a productive loop.</p>

<h2 id="my-workflow-today">My workflow today</h2>

<p>My workflow looks like:</p>

<ol>
  <li>Write up a design or prompt (I usually like to document my actual written prose somewhere, usually a DESIGN.md).</li>
  <li>Ask Cursor / Claude / Gemini to implement it.</li>
  <li>Review the code, ask it to fix things. Back to 1 if needed.</li>
  <li>Validate the feature e2e. Back to 1 if needed.</li>
  <li>Commit and push.</li>
</ol>

<p>I’d argue this is very hands-on. But even with this level of micro-managing, I get a ton of changes done in a short period. Over 1.5 hours on a random Saturday, I got through 7 feature requests in <a href="https://github.com/aep-dev/aep-e2e-validator/commits/main/">aep-e2e-validator</a>, and I felt good about the code and the result of those. Probably 3-4x what I could with a coding-first approach, and with probably one half of the mental load.</p>

<p>Oh, and I also created a code extension to fill in some missing gaps I had in openvsx (https://github.com/toumorokoshi/code-fileclrk). And a couple bugs in other repositories. So I guess that’s more like 10 contributions in a 1.5 hour period, and a 5x increase?</p>

<p>Regardless the multiplier at this point is astounding. As Steve said in his blog post, the bottleneck here really is no longer the code.</p>

<h2 id="my-workflow-in-the-future">My workflow in the future</h2>

<p>I thought the above was great, but then I read GasTown. To be clear, I am a still a pessimist on AI, so I don’t want to say I’ve drunk the Kool-aid just yet. But the extremely detailed post helped me really understand what an 100x future could look like. It’s basically layers of abstractions, but with AI agents filling almost every single piece of the puzzle:</p>

<ul>
  <li>agents are writing code.</li>
  <li>agents are reviewing PRs.</li>
  <li>agents are helping summarize the changes and writing them out to a record of what decisions were made.</li>
  <li>you talk to an agent to help dispatch these tasks to other agents.</li>
</ul>

<p>And so on - multiple role-based agents, that fill whatever gap you’ve encountered with the other agents you’ve already deployed. Assuming the agent is good enough, or you’ve anchored the manual review to the point of no return (e.g. before performing a financial transaction, or perhaps cutting a release), you could delegate the next level of review over and over again.</p>

<p>And intuitively - this kind of makes a wacky kind of sense, where you are <em>abstracting yourself to the point where you are focusing on the problem where human judgement is truly needed</em>. In the past, for someone to get something accomplished with software, you had to work on every single piece by hand (perhaps except the hardware you run on). But now, if there’s a task you don’t find particularly appealing, and as long as you’re willing to do some manual review, you can definitely delegate that to an agent!</p>

<h3 id="the-caveat-you-need-the-domain-knowledge-to-succeed">The caveat: you need the domain knowledge to succeed</h3>

<p>Some might read the above and believe that this means that an individual does not need the same skills that the agent does. For example, a non-technical person can write software. I don’t really believe that’s the case, at least not 100%.</p>

<p>For one, it’s important to know that there are just some concerns that are so mission-critical that you cannot reasonably accomplish that without some sort of expertise or awareness. Those are:</p>

<ul>
  <li>Proper resource management, quotas, and monitoring so you don’t get a giant check that backrupts you.</li>
  <li>Security. If your service is compromised, the damage is irreperable.</li>
</ul>

<p>But there’s a huge swath of things that you don’t really have to understand too deeply at the beginning. And as long as you have the skills and time to dive in, AI could take the first swag at it:</p>

<ul>
  <li>command-line interfaces.</li>
  <li>applications that run locally.</li>
  <li>any codebases that have significant guardrails (linting / testing / etc).</li>
</ul>

<h2 id="final-thoughts">Final Thoughts</h2>

<h3 id="so-what-is-the-bottleneck-now">So what is the bottleneck now?</h3>

<p>It feels like the bottleneck now is the human’s ability to reason about a problem and figure out a good solution. I suppose one can argue that human reasoning was always the bottleneck, but I think the abstraction is at a higher level now.</p>

<p>Oh, and money / energy. You can produce as much as you have money to pay for an agent to generate for you. That or your human ability to think about these problems, which limits you first.</p>

<h3 id="human-interaction-is-still-needed">Human interaction is still needed</h3>

<p>In this fever dream of AI, there are no humans. But to make real change happen in an organization, you still need to talk to people, and that’s the real challenge.</p>

<p>Pretty much everything that has real impact, to some extent, requires thoughtful interaction with others:</p>

<ul>
  <li>Getting buy-in on the idea.</li>
  <li>Getting others to use it (sharing demos, recordings, talking to people in 1-1s and through slack).</li>
  <li>Getting approvals to merge or ship the code.</li>
  <li>Getting the team that owns the product to accept your idea and put it on their roadmap (or accept your code).</li>
</ul>

<p>So although some coding is trivial now, I don’t believe that the bulk of the my work, for example, is removed. Communication and interaction with individuals is still key.</p>

<h3 id="agents-give-us-the-freedom-to-dive-into-the-problem-we-want-to">Agents give us the freedom to dive into the problem we want to</h3>

<p>Perhaps there is a world where someone chooses to completely ignore code or a particular engineering problem algother. But I don’t really see this as my motivation.</p>

<p>I think agents provide us the freedom to work on the problems we want to, or perhaps minimize the time we spend on the problems we don’t want to work on. We have a fairly autonomous coder / problem solver than can get things <em>mostly</em> right, and we can trust if we need to.</p>

<p>But if we want to, we can dive right in! And there’s reasons to do so: the code may have gotten too messy, the abstractions are not easily understood, or the code is not performant.</p>

<p>And if you want to assert that level of control and code something yourself, you can! So again, in some ways it’s refreshing in that you can spend more of your time on the problems <em>you</em> care about, not just the rote ones that need to be done.</p>

<h3 id="when-and-how-will-we-get-to-this-glorious-future">When and how will we get to this glorious future?</h3>

<p>So when can we get to this world where agents completely autonomously write their own code and produce real, working products?</p>

<p>I think for some software engineers, they’re basically there today. GasTown seems like it’s run fairly automated with agents working on it all the time. I don’t think throwing agents at compilers and browsers has produced a working product either.</p>

<p>For me personally, I don’t know if I have a project that really is accelerated by 100 autonomous agents all writing code. But I’d like to start climbing this maturity ladder to see if I can squeeze out a little bit more of that time to think about the problems I’m really interested in diving into.</p>]]></content><author><name></name></author><category term="coding" /><summary type="html"><![CDATA[The new AI Era]]></summary></entry><entry><title type="html">DUGS: Data Uniquess via Gradient Similarity</title><link href="https://y.tsutsumi.io/dugs" rel="alternate" type="text/html" title="DUGS: Data Uniquess via Gradient Similarity" /><published>2026-03-08T07:00:00+00:00</published><updated>2026-03-08T07:00:00+00:00</updated><id>https://y.tsutsumi.io/data-uniqueness-via-gradient-similarity-dugs</id><content type="html" xml:base="https://y.tsutsumi.io/dugs"><![CDATA[<h1 id="data-uniqueness-via-gradient-similarity">Data Uniqueness via Gradient Similarity</h1>

<h2 id="summary">Summary</h2>

<p>This post outlines an experiment I ran to try to better understand the unique data inputs I’m using for model training. This is a modification of DVGS - “Data Valuation via Gradient Similarity”, that I’m calling DUGS (data uniquess via gradient simlarity).</p>

<h2 id="algorithm-high-level">Algorithm high level</h2>

<p>The high level idea is:</p>

<ol>
  <li>Grab the following:
a. An already trained model
b. A random sampling of the data you would like to evalute of size X</li>
  <li>Initialize a map of <code class="language-plaintext highlighter-rouge">{data_point_id, uniquess_dimension}</code> to store differing data points.</li>
  <li>Run a training pass on each datapoint. Calculate the gradient up to a layer Z.</li>
  <li>Reduce the dimensionality of that vector via a random matrix <code class="language-plaintext highlighter-rouge">{gradient_size, uniqueness_dimension}</code> to reduce the cost of calculating gradient similarity. (Johnson-Lindenstrauss projections)</li>
  <li>Use cosine similarity to compare it to existing vectors in the list
    <ol>
      <li>if the similarity is less than some threshold (0.3 by default) from any of the previous data points, add the new data point to the list.</li>
    </ol>
  </li>
</ol>

<h2 id="tunable-parameters">Tunable parameters</h2>

<h3 id="data-set-size">Data Set Size</h3>

<p>The size of the data set you are running the evaluation on will affect the runtime of the algorithm linearly.</p>

<h3 id="uniqueness-dimension-via-johnson-lindestrauss-lemma-error">Uniqueness dimension via Johnson-lindestrauss lemma error</h3>

<p>The smaller the dimension size you can reduce to, the more efficient the calculation is.</p>

<p>The Johnson-Lindenstrauss Lemma states that preserving the vector dimensionality within an error bound <code class="language-plaintext highlighter-rouge">e</code> for a dataset size <code class="language-plaintext highlighter-rouge">N</code> is calculated as:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>k &gt; (8 * ln(N) / e^2)
</code></pre></div></div>

<p>Although we are only seeking a limited number of datasets, making this match the target <em>full dataset</em> size ensures that there is sufficient dimensionality to understand the nuances between the dataset. The main tunable parameter is the margin of error introduced by the reduction of matrix for comparison.</p>

<p>For example, for 10,000 images, and a desired error of 0.001, you would have to have a base 2 dimension of roughly <code class="language-plaintext highlighter-rouge">8 * ln(10000) / (0.001^2)) = 73682722</code>, or somewhere between 2^26 ~ 2^27 (rounding to some base 2 size matrix is preferred to align with scheduling on processors which primarily have cache sizes, multithreaded processor / code SM counts that align to some multiple of 2).</p>

<h3 id="number-of-layers-to-backpropagate">Number of layers to backpropagate</h3>

<p>This one is a model-specific choice: the more layers that backpropagation is run, the runtime complexity will multiplied by the cost to compute the backpropagation of that layer.</p>

<p>As a rule of thumb, I think you want to only go back to the number of a relatively low number of layers: there is an intuition that the later layers of a model are the ones more correlated to fine-tuned behavior for the specific task. This is probably the behavior that one is most interested in, such as wehn trying to find more datapoints of similar, but underrepresented data, to increase the distribution thereof.</p>

<h2 id="results">Results</h2>

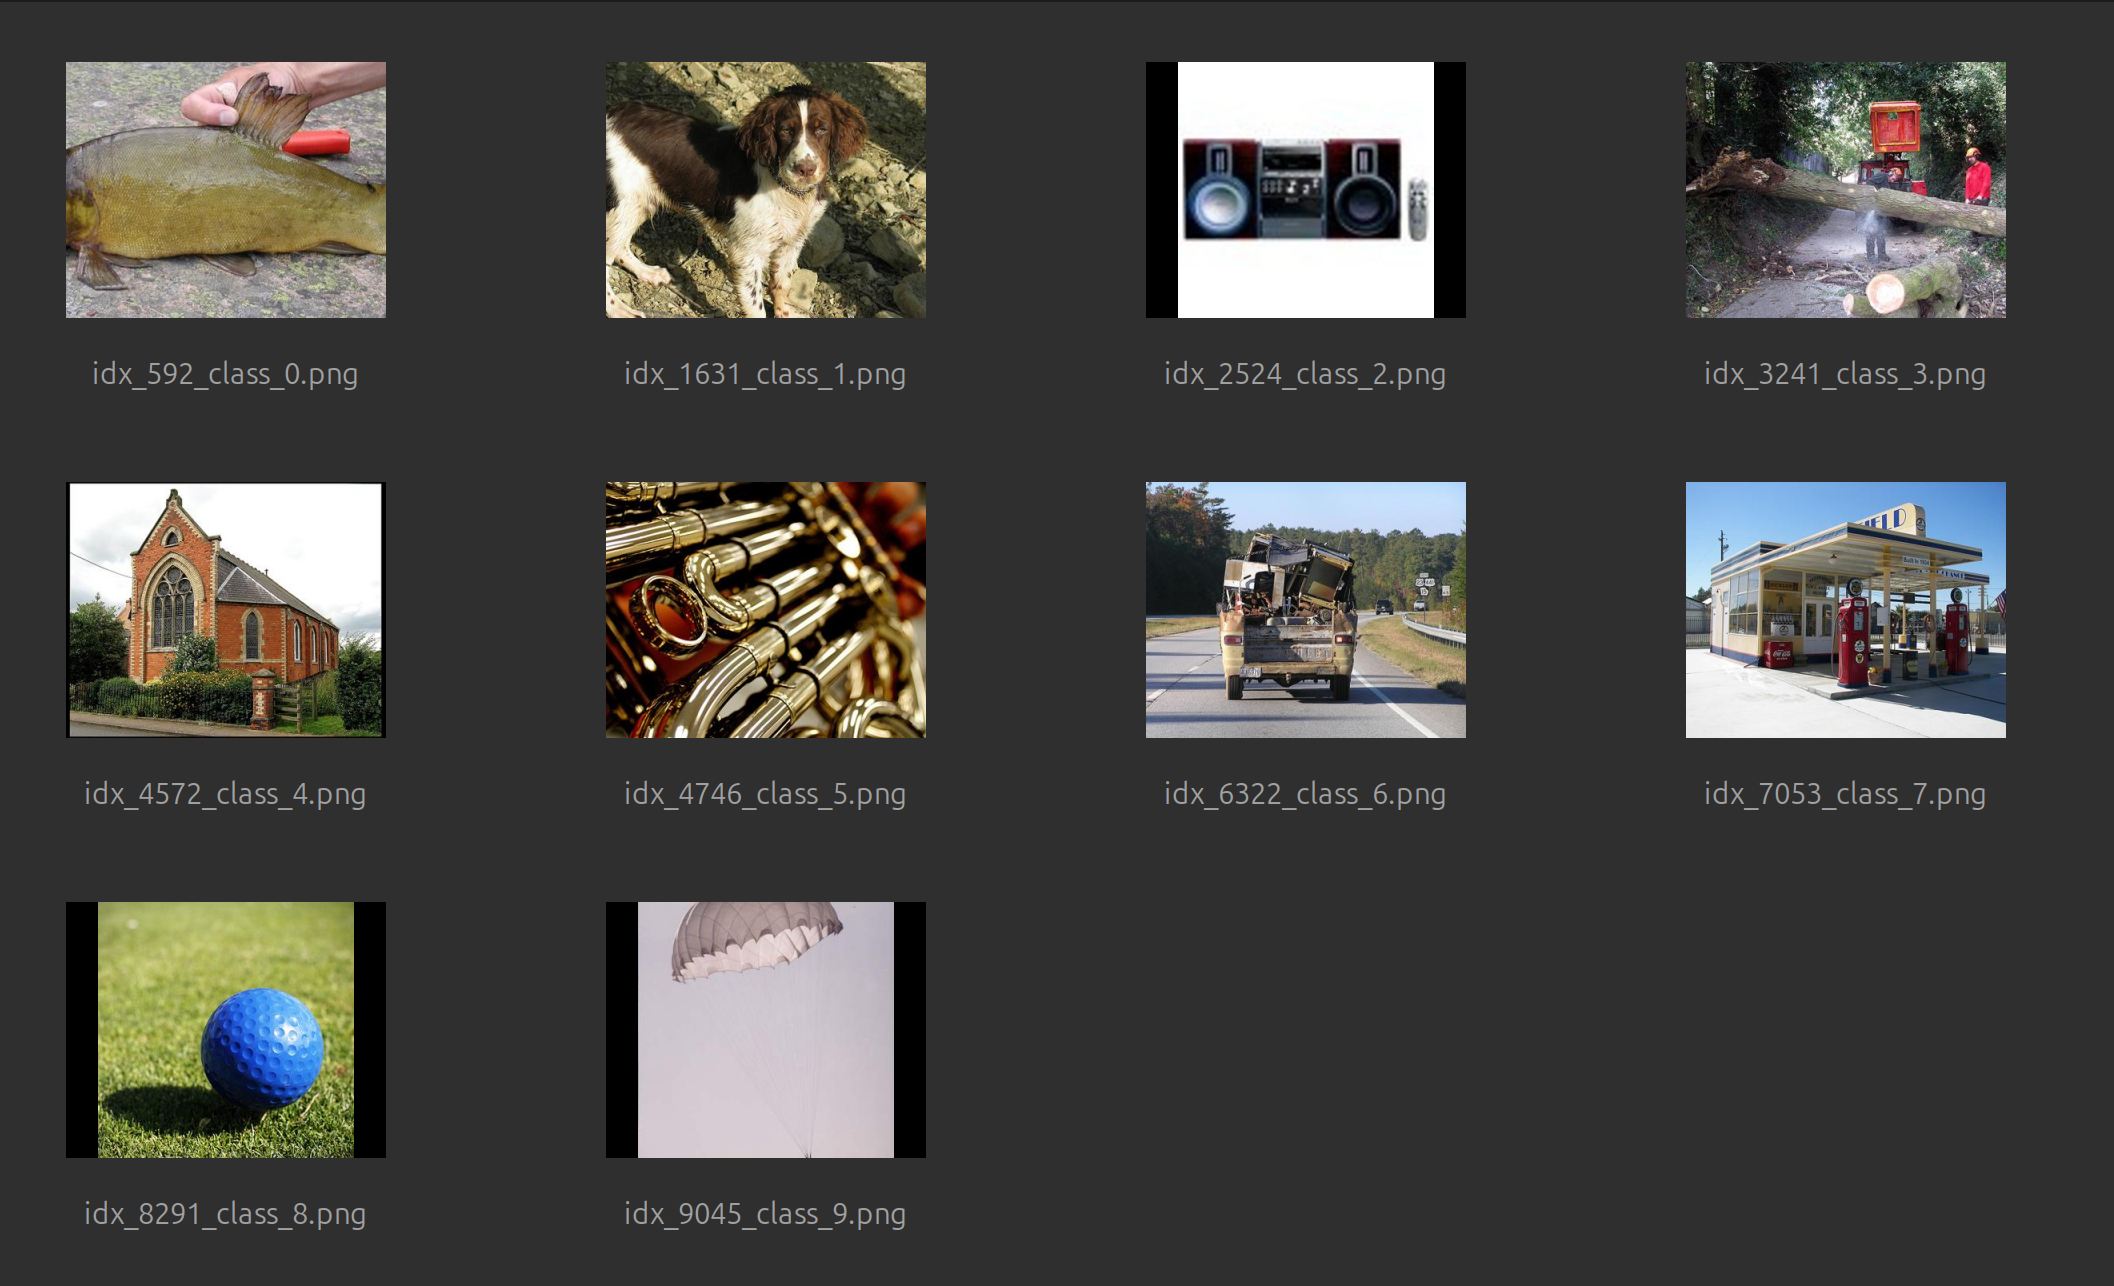
<p>I tried this out in my sandbox against my toy model <a href="https://github.com/toumorokoshi/yft-ml-sandbox/tree/main/alexnet_dvgs">based on AlexNet</a>, which uses the <a href="https://github.com/fastai/imagenette">Imagenette dataset</a>. Looking at the results visually, it looks like it was able to differentiate and find examples of each of the 10 categories:</p>

<p><img src="../../assets/2026-03-08-data-uniqueness-via-gradient-similarity-dugs.png" alt="2026-03-08-data-uniqueness-via-gradient-similarity-dugs.png" /></p>

<h3 id="future-experiments-to-try">Future Experiments to try</h3>

<ul>
  <li>focus on the gradient of a specific layer (e.g. the embeddings)</li>
  <li>use dimensionality reduction via Johnson-Lindenstrauss projections</li>
  <li>can we use some form of k means clustering to help group the data points?
    <ul>
      <li>this would be helpful to see how many “categories” of data there are.</li>
    </ul>
  </li>
</ul>]]></content><author><name></name></author><category term="coding" /><category term="ml" /><summary type="html"><![CDATA[Data Uniqueness via Gradient Similarity]]></summary></entry><entry><title type="html">Setting up Hibernate on Linux</title><link href="https://y.tsutsumi.io/setting-up-hibernate-linux" rel="alternate" type="text/html" title="Setting up Hibernate on Linux" /><published>2026-02-23T07:00:00+00:00</published><updated>2026-02-23T07:00:00+00:00</updated><id>https://y.tsutsumi.io/setting-up-hibernate-linux</id><content type="html" xml:base="https://y.tsutsumi.io/setting-up-hibernate-linux"><![CDATA[<h1 id="setting-up-hibernate-on-linux">Setting up Hibernate on Linux</h1>

<p>My Framework 13 laptop has an issue where the battery drains very quickly, even when sleeping.</p>

<p>This seems to be a known issue with Framework laptops. Since I often just use my work computer during the weekdays, the laptop is dead before I can use it again.</p>

<h2 id="reviewing-sleep-states-available">Reviewing sleep states available</h2>

<p>In Linux, there are specific levels of sleep states that can be used:</p>

<ul>
  <li>freeze (S0ix)</li>
  <li>standby (S1): rarely used in modern systems.</li>
  <li>mem (S3): hardware is powered off except ram.</li>
  <li>disk (S4): hibernate. system state is moved to disk.</li>
</ul>

<h2 id="checking-power-states-available">Checking power states available</h2>

<p>First I checked what was available with:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">cat</span> /sys/power/state
<span class="c"># freeze mem</span>
</code></pre></div></div>

<p>So freeze and mem are available.</p>

<h2 id="configuring-hibernate-with-luks">Configuring hibernate with LUKS</h2>

<p>I like to use LUKS (Linux Unified Key Setup) to encrypt my drives. To do so with hibernate, the following workflow is required:</p>

<ol>
  <li>use the bootloader to loader the initramfs</li>
  <li>have the initramfs decrypt the LVM volume that contains the main partition as well as swap.</li>
  <li>the initramfs detects that the swap partition is available and restores the system state from it, if a hibernate image is found.</li>
</ol>

<h3 id="configuring-the-partitions">Configuring the partitions</h3>

<p>The final partition structure will look something like:</p>

<ul>
  <li>/dev/nvme0n1p1 (EFI / bootloader)</li>
  <li>/dev/nvme0n1p2 Linux filesystem partition: an unencrypted boot partition that contains the OS needed to perform the decryption of the encrypted drive.</li>
  <li>/dev/nvme0n1p3 Linux filesystem partition: the encrypted disk partition.
    <ul>
      <li>/dev/mapper/dm-crypt-0
        <ul>
          <li>/dev/mapper/ubuntu–vg-ubuntu–lv: the actual OS.</li>
          <li>/dev/mapper/swap: the swap space that the partition will hibernate to.</li>
        </ul>
      </li>
    </ul>
  </li>
</ul>

<h2 id="steps">Steps</h2>

<p><em>NOTE</em>: these were with my install of ubuntu 25.10. YMMV.</p>

<h3 id="resize-the-partition-and-make-a-swap-partition">Resize the partition and make a swap partition</h3>

<ol>
  <li>use a live USB so I can modify the partition</li>
  <li>open the luks partition: <code class="language-plaintext highlighter-rouge">sudo cryptsetup open ${partition} ${lvm-volume-name}</code></li>
  <li>reduce the size: <code class="language-plaintext highlighter-rouge">sudo lvreduce -r -L -128G /dev/mapper/${root-lvm-partition}</code></li>
  <li>create the volume: <code class="language-plaintext highlighter-rouge">sudo lvcreate -L 128G -n swap ${lvm-volume-name}</code></li>
  <li>format as swap: <code class="language-plaintext highlighter-rouge">sudo mkswap /dev/mapper/${swap-lvm-partition}</code></li>
</ol>

<h3 id="make-the-partition-swap">Make the partition swap</h3>

<p>This ensures the swap partition is available on boot to suspend to.</p>

<p>When back into the OS:</p>

<ol>
  <li><code class="language-plaintext highlighter-rouge">sudo swapon /dev/mapper/${swap-partition-name}</code></li>
  <li>Update <code class="language-plaintext highlighter-rouge">/etc/fstab</code> to mount the swap on boot:</li>
</ol>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>/dev/mapper/{swap-partition-name} none swap sw 0 0
</code></pre></div></div>

<h3 id="set-the-swap-partition-as-a-hibernate-partition">set the swap partition as a hibernate partition</h3>

<p>This tells the kernel where to look for the hibernate image when resuming.</p>

<ol>
  <li>modify <code class="language-plaintext highlighter-rouge">GRUB_CMDLINE_LINUX_DEFAULT</code> in <code class="language-plaintext highlighter-rouge">/etc/grub/config</code> with:</li>
</ol>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>resume=/dev/mapper/{swap-partition-name}
</code></pre></div></div>

<ol>
  <li>run <code class="language-plaintext highlighter-rouge">sudo update-grub</code></li>
</ol>

<h3 id="enable-hibernate-in-the-linux-kernel-image">enable hibernate in the linux kernel image</h3>

<p>This is required for the initramfs to know how to restore from the hibernate image.</p>

<ol>
  <li>create file <code class="language-plaintext highlighter-rouge">/etc/initramfs-tools/conf.d/resume</code> with:</li>
</ol>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>RESUME=/dev/mapper/{swap-partition-name}
</code></pre></div></div>

<ol>
  <li>run <code class="language-plaintext highlighter-rouge">sudo update-initramfs -u -k all</code></li>
</ol>

<h3 id="disable-secure-boot">disable secure boot</h3>

<p>The last step is to disable secure boot in the BIOS.</p>

<p>Theoretically there is a way to sign the hibernated image with a TPM (trusted partner module) or a MOK (machine-only-key), but I didn’t want to have to re-encrypt my volume.</p>

<h2 id="conclusion">Conclusion</h2>

<p>Success! After the above, I can now hibernate my laptop.</p>

<p>Even with my 64GB of RAM, the hibernate / restore has been pretty quick so far: roughly 20 seconds at most to come back up from a full hibernate. Good solution for laptops I use once in 24 hours.</p>]]></content><author><name></name></author><category term="linux" /><category term="hibernate" /><summary type="html"><![CDATA[Setting up Hibernate on Linux]]></summary></entry><entry><title type="html">My Diet in 2026</title><link href="https://y.tsutsumi.io/diet" rel="alternate" type="text/html" title="My Diet in 2026" /><published>2026-02-16T07:00:00+00:00</published><updated>2026-02-16T07:00:00+00:00</updated><id>https://y.tsutsumi.io/diet-2026</id><content type="html" xml:base="https://y.tsutsumi.io/diet"><![CDATA[<p>This is are some notes about what I eat, how I eat, and why.</p>

<p>see <a href="/diet/2022">/diet/2022</a> for an older version of this article.</p>

<h2 id="short-checklist">Short checklist</h2>

<ul>
  <li>Vegan diet</li>
  <li>Drink caffeinated drinks (e.g. coffee) to suppress appetite, and to <a href="https://medicine.nus.edu.sg/news/caffeine-helps-restore-memory-function-after-sleep-loss-nus-medicine-study-shows/">help combat memory loss</a>.</li>
  <li>Sodas are a great way to suppress appetite.</li>
  <li>Target 1.6g protein / kg body weight day.</li>
  <li>Target 45g fiber / day.</li>
  <li>Try to get as close to zero for saturated fat intake.</li>
  <li>Target 1400kcal for cutting, 1800kcal for bulking.
    <ul>
      <li>when bulking, do a slow bulk to build muscle.</li>
    </ul>
  </li>
  <li>targetting low carb diet (50 carbs / day).</li>
  <li>Moderate sodium intake</li>
  <li>Try to hit 100% RDA on potassium (this is very, very hard): this helps counteract bloating caused by sodium.</li>
</ul>

<h2 id="example-diets">Example diets</h2>

<table>
  <thead>
    <tr>
      <th>Food</th>
      <th>Calories</th>
      <th>Protein</th>
      <th>Fiber</th>
      <th>Carbs</th>
      <th>Time</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1/2 Soy Latte (180ml) + fiber</td>
      <td>32</td>
      <td>2.5</td>
      <td>4</td>
      <td>0.5</td>
      <td>8:00am</td>
    </tr>
    <tr>
      <td>Keto Bread + 60g Protein Spread</td>
      <td>100</td>
      <td>16</td>
      <td>8</td>
      <td>3</td>
      <td>10:00am</td>
    </tr>
    <tr>
      <td>Sparkling water or diet soda</td>
      <td>0</td>
      <td>0</td>
      <td>0</td>
      <td>0</td>
      <td>11:30am</td>
    </tr>
    <tr>
      <td>Keto Bread + 50g Protein Spread</td>
      <td>100</td>
      <td>16</td>
      <td>8</td>
      <td>3</td>
      <td>12:00am</td>
    </tr>
    <tr>
      <td>1/2 Soy Latte (180ml) + fiber</td>
      <td>32</td>
      <td>2.5</td>
      <td>4</td>
      <td>0.5</td>
      <td>1:00pm</td>
    </tr>
    <tr>
      <td>Huel Black (1/2 serving)</td>
      <td>200</td>
      <td>20</td>
      <td>4</td>
      <td>9</td>
      <td>2:00pm</td>
    </tr>
    <tr>
      <td>Powder</td>
      <td>120</td>
      <td>20</td>
      <td>4</td>
      <td> </td>
      <td>4:00pm</td>
    </tr>
    <tr>
      <td>Keto Bread + 50g Protein Spread</td>
      <td>100</td>
      <td>16</td>
      <td>8</td>
      <td>3</td>
      <td>5:00pm</td>
    </tr>
    <tr>
      <td>whatever for 20g protein defecit</td>
      <td>??</td>
      <td>??</td>
      <td>?</td>
      <td> </td>
      <td>after work</td>
    </tr>
    <tr>
      <td>Total</td>
      <td>840g</td>
      <td>100g</td>
      <td>45g</td>
      <td> </td>
      <td> </td>
    </tr>
  </tbody>
</table>

<h2 id="major-ideas">Major Ideas</h2>

<h3 id="mostly-vegan-plant-based-diet">Mostly vegan (plant-based diet)</h3>

<p><a href="https://y.tsutsumi.io/2020/03/04/book-report-the-blue-zones/">People who eat a plant-based diet live 7 years longer</a>.</p>

<p>It’s hard for me to go completely vegan (I like my seafood and dairy), so I try to go for vegan meals most of the week at home. When I eat out I eat vegetarian or seafood.</p>

<p>From what I read in Blue Zones (above), eating meat once a week still helps you get a lot of the longevity benefits.</p>

<p>Those who have plant-based high protein diets also tend to have better kidney health than those who dairy / meat based high protein diets.</p>

<h3 id="high-protein">High-protein</h3>

<p>I eat 1.6 grams of protein per 1KG of body weight a day at minimum. Studies have shown that this is the amount that has shown to maximize muscular hypertrophy. I strive to maximize muscle mass ultimately for increasing my healthspan.</p>

<p>With a vegan diet, that number likely should be higher: vegan proteins are not always complete, and may not be in an easily digestable form unlike meat.</p>

<p>However, I do strive for foods that have a <a href="https://en.wikipedia.org/wiki/Digestible_Indispensable_Amino_Acid_Score">diaas score</a> close to 1 or greater:</p>

<ul>
  <li>soy protein isolate, soybeans, soymilk, tofu.</li>
  <li>pea protein.</li>
  <li>beans (kidney, fava).</li>
</ul>

<h3 id="targetting-caloric-restriction">Targetting Caloric Restriction</h3>

<p>I’m currently in the middle of trying to lose weight: my last Dexa scan in 2022/10 put me at 21% body fat, which is much higher than I’m hoping. My current target is 15% body fat, which means I have to lose 12 lbs of body weight.</p>

<p>To that end, I’m looking at some minor caloric restriction: at 1700 kcal / day, and assuming I can build up a daily caloric expendature of 2100 kcal, that would be me at 3500 / (2100 - 1700) ~ 8.75 days to lose a pound of weight. And ideally I could my weight in 108 days (~4 months).</p>

<p>I’m mixing that with lifting weights to try to guarantee muscle hypertrophy.</p>

<p>In reality my caloric intake is often higher due to limited self-control, but I’m working on that.</p>

<h2 id="other-tips">Other Tips</h2>

<h3 id="sucralose-may-cause-nafld">Sucralose may cause NAFLD</h3>

<p>When I started eating four servings of Huel protein powder a day (to try to up
my protein intake, those 80 grams help) along with drinking a sugar-free sweet
coffee daily, I found that my ALT and AST numbers have grown significantly
(11-&gt;16 and 17-&gt;25, respectively over 10 months).</p>

<p>I’m not sure the precise cause, by after doing some research I found some
research in mice that shows sucralose and stevia (and regular sugar) consumption
increasing ALT and AST.</p>

<p>Correlation is not causation, but I’m currently (2023/04) trying to lower my
Sucralose consumption significantly to see if my numbers change at all.</p>

<h2 id="only-allulose-and-stevia-for-non-nutritive-sweeteners">Only Allulose and Stevia for non-nutritive sweeteners</h2>

<p>Several non-nutritive sweeteners have downsides:</p>

<ul>
  <li>Aspartame may cause an insulin response.</li>
  <li>Erithrytol may cause blood clotting, and impact the blood/brain barrier.</li>
  <li>Sucralose may cause NAFLD.</li>
</ul>

<p>Which leaves a limited set of non-nutritive sweeteners to choose from:</p>

<ul>
  <li>Allulose</li>
  <li>Stevia</li>
</ul>

<h2 id="specific-food-recommendations">Specific Food Recommendations</h2>

<p>To hit a 50 carb target with 1400 kcal, you need to target foods that provide
roughly 1 carb per 26 kcal or less.</p>

<p>Also, unlike most low carb diets, I prefer to stay low in saturated fat as well.
It’s a hard balance but I try to make sure these foods have relatively low
saturated fat.</p>

<p>For my specific dietary preferences, my recommendations are:</p>

<table>
  <thead>
    <tr>
      <th>Food</th>
      <th>Calories</th>
      <th>Protein</th>
      <th>Fiber</th>
      <th>Carbs</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1/2 Soy Latte (180ml) + inulin fiber</td>
      <td>32</td>
      <td>2.5</td>
      <td>2</td>
      <td>0.5</td>
    </tr>
    <tr>
      <td>Huel Black (1/2 serving)</td>
      <td>200</td>
      <td>20</td>
      <td>4</td>
      <td>9</td>
    </tr>
    <tr>
      <td>Nature’s own Keto Bread</td>
      <td>35</td>
      <td>6</td>
      <td>9</td>
      <td>1</td>
    </tr>
    <tr>
      <td>Simple Truth Protein Crackers</td>
      <td>120</td>
      <td>10</td>
      <td>6</td>
      <td>4</td>
    </tr>
    <tr>
      <td>Almonds</td>
      <td>160</td>
      <td>6</td>
      <td>3</td>
      <td>3</td>
    </tr>
    <tr>
      <td>Spinach (100g)</td>
      <td>23</td>
      <td>2.9</td>
      <td>2.2</td>
      <td>3.6</td>
    </tr>
  </tbody>
</table>

<h3 id="nespresso">Nespresso</h3>

<p>I like to drink Nespresso every morning. I generally may make a mezzo (half
americano, half soy latte) with the following:</p>

<ul>
  <li>Mezzo with Tropical Coconut Flavor + 180ml soy milk.</li>
  <li>Straight: Peppermint Pinwheel.</li>
  <li>Bianco Doppio with 120ml milk.</li>
  <li>2x Altissio with 180ml milk (I like this because they offer a decaf option).</li>
</ul>

<p>Sometimes I replace the soy with a larger volume of macadamia milk (fewer
calories).</p>

<h3 id="good-foods">Good Foods</h3>

<ul>
  <li>Pistachio: relatively lower carbs, low saturated fat, high potassium.
    <ul>
      <li>
        <h2 id="high-phosphorous-so-try-to-eat-it-in-moderation">high phosphorous so try to eat it in moderation.</h2>
      </li>
    </ul>
  </li>
</ul>]]></content><author><name></name></author><category term="diet" /><category term="health" /><summary type="html"><![CDATA[This is are some notes about what I eat, how I eat, and why.]]></summary></entry></feed>